
We build AI agents you can check
Two weeks, €3,000 fixed, one task — an agent doing that task on your own data, with a number on how often it gets it right and a list of what it gets wrong. If it does not pay for itself, we say so on day three and there is nothing to pay.
Agents we have shipped
An agent is given a job, fetches what it needs, works through the steps, and returns a draft, a filled-in record or a finished report for a person to approve or reject. We score agents on real test sets before they ship, test inputs that were not selected for a demo, keep an audit trail of what they did, and pressure-test them against prompt-injection attacks.
- Multi-agent
A six-agent pipeline
OpenClaw runs insurance claims through six agents with a Run → Eval → Improve loop, and an LLM judge scores every pass.
View the code ↗- Auditable
An on-chain agent you can check
Trustodian enforces a spending mandate and leaves a trail you can audit after the fact. Second place at The Money Agent Hackathon.
- Adversarial-tested
Built to resist attacks
Our BitGN agent has to finish ordinary tasks while refusing the prompt-injection traps hidden inside them, and it's scored by what it actually changed.
View the code ↗- In production
Running for real users
A nutrition agent lives in a live chat with memory and context, shipped only after we widened its eval set. A team of agents reads location data to write sourced expansion briefs for a retail-analytics product. And an offer agent builds a uniform manufacturer's client offers from their own catalogue, showing the plan before it spends anything.
What goes into an agent that holds up
We offer three services around an agent: build one agent for one task and prove it pays, give it access to what the company actually knows, and measure what it gets wrong before release. They can be used together or bought separately, depending on what you already have.
01
Agent Build
Two weeks, one task, one working agent on your own data. The first days settle which task pays for itself and end on a go/no-go — if the answer is no, there is nothing to pay. The rest builds the winner against a test set of your real cases. Code, test set and numbers are yours.
How the build works →Proven by
- Catalogue-to-Offer Agent for a Uniform Manufacturer
A production workflow connecting catalogue articles, approved plans, visual checks and saved revisions, with a person choosing the images and accepting the exact files used in the final PDF.
- Country Explorer: Location Intelligence for Restaurants
A team of agents reads location, footfall and demographic data and writes sourced expansion briefs a human can check against the figures behind them.
- LetAI: Nutrition Estimation Agent in Production Chat
The agent only reached production chat after its evaluation pipeline was expanded, with new datasets and broader case coverage added before release.
- Catalogue-to-Offer Agent for a Uniform Manufacturer
02
Knowledge Base (RAG)
Your own documents start answering questions, and every answer links back to where it came from. We agree on a test set up front and show you the quality numbers before handover.
How we build it →Proven by
- Expert Blockchain Chatbot
Production RAG with quality we measured. Retrieval goes past plain vectors (SQL, entity lookup, real-time data), and an evaluation framework (RAGAS) scores the answers.
- AI Stylist: Fashion Attributes from Expert Video
Expert video turned into structured, queryable data, backed by the product's first labeled garment-image dataset.
- Jazion: An AI Copilot for Language Tutors
Turns recorded lessons into structured, queryable knowledge: a summary, lesson card, Q&A, and quizzes delivered to students automatically.
- AI Book Recommendation Assistant
Answers come from a live product database. Hybrid retrieval (RecSys, vector search, and LLMs) does the work, so the model isn't guessing from memory.
- Expert Blockchain Chatbot
03
Evals / QA
We build test sets from your real cases and score your AI the same way on every release, so a drop in quality shows up before your users run into it.
How evals work →Proven by
- Expert Blockchain Chatbot
Production RAG with quality we measured. Retrieval goes past plain vectors (SQL, entity lookup, real-time data), and an evaluation framework (RAGAS) scores the answers.
- LetAI: Nutrition Estimation Agent in Production Chat
The agent only reached production chat after its evaluation pipeline was expanded, with new datasets and broader case coverage added before release.
- Market Analyst for a Chemical Manufacturer
Recommends what to produce next on evidence a buyer can re-check: every figure traced to its source row and cleared by named quality gates.
- zebra_simple: Zebra Puzzle Test for LLMs
Our published LLM reasoning benchmark. It's open evidence, and anyone can check it.
- Expert Blockchain Chatbot
Built for one industry
Offer sheets for uniform makers
A one-line brief in chat comes back as a branded offer sheet. It uses the manufacturer's own garments and the client's brand colours, in their sheet format, in Serbian or English.
It has been running on their real client work since July 2026.
See what it does →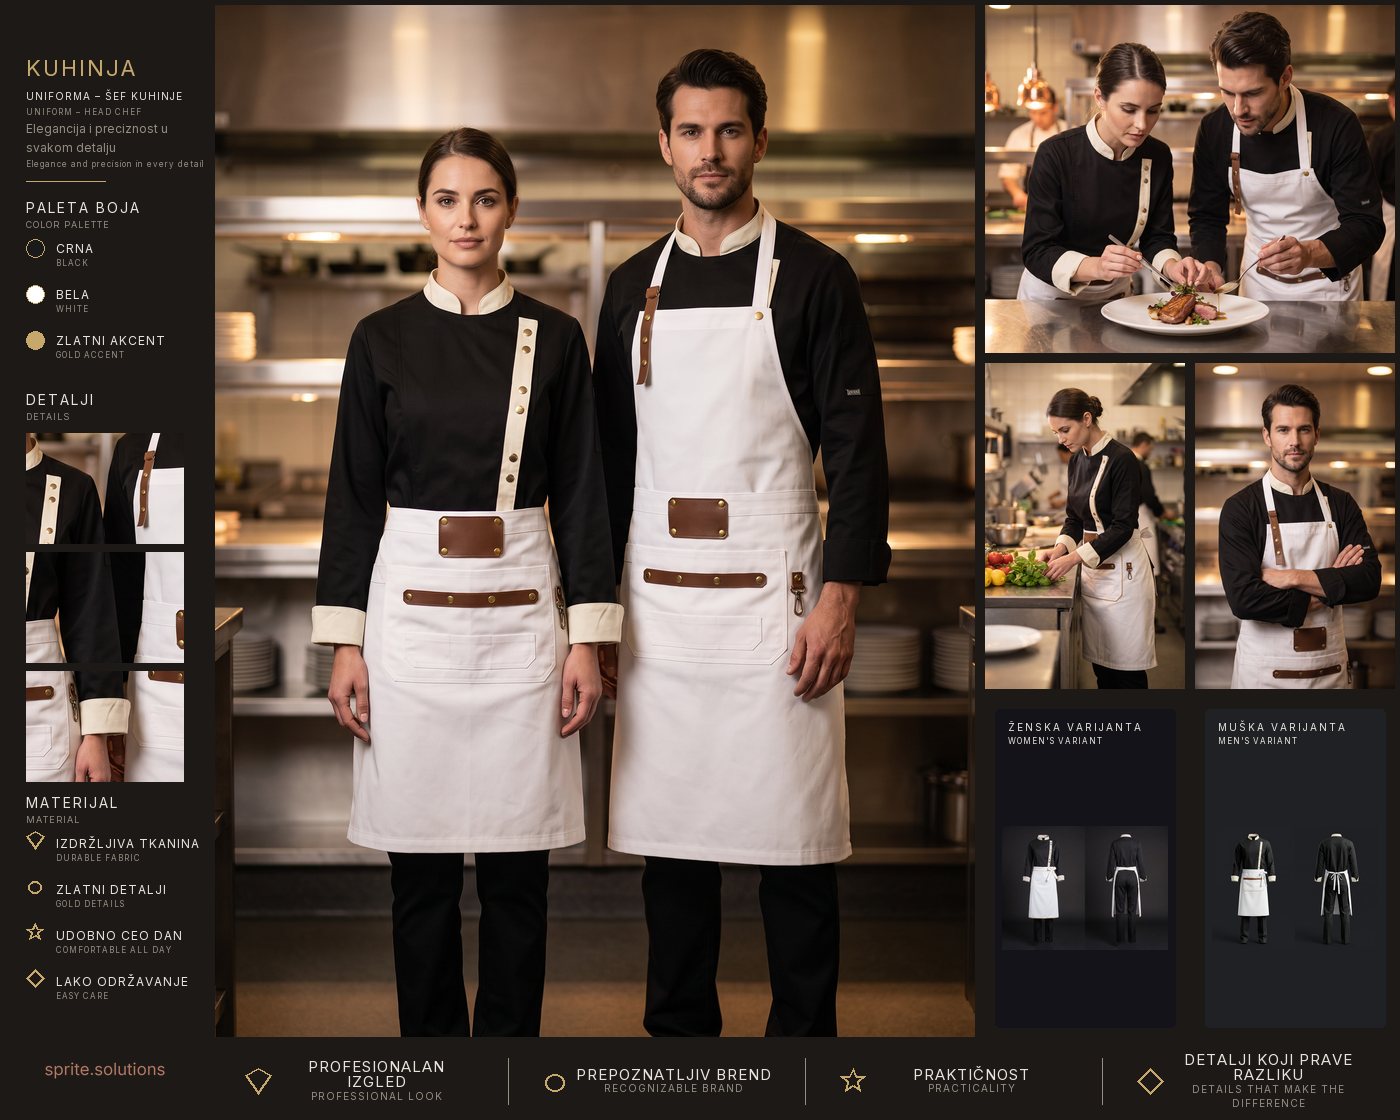
Built by researchers who ship
PhD-trained researchers and engineers who compete in the open and publish what they build. Each line below is a result someone other than us can look at.
3rd / 155 teams
ARLC 2026 warm-up phase, scoring 0.954/1.0, with an agentic RAG pipeline for legal AI ↗
2nd place
The Money Agent Hackathon — Trustodian, an auditable on-chain agent with mandate enforcement
1st, Serbian hub
The BitGN PAC personal AI agent challenge, which drew 800+ entrants overall ↗
Six agents
Open source
FPF-agent — a Claude Code plugin for structured reasoning, code public on GitHub ↗
Published
When an agent fits the task
The task needs to happen often enough, and take enough staff time, for the build to pay for itself. It also needs a named owner inside your company after handover. If what you need is a chat widget on your site, ready-made products are available at software prices. The first days of a build are a go/no-go: if none of your candidate tasks pays for itself, we say so on day three and there is nothing to pay.